A good testing strategy is not a contest to produce the largest test suite. It is a deliberate way to answer one question: what evidence does this team need before it can change the system with confidence?
I have seen teams with thousands of tests hesitate before every release because the suite is slow and unreliable. I have also seen smaller suites protect critical behaviour extremely well. The difference is rarely the framework. It is whether the tests reflect the product’s risks, architecture, and delivery process.
The short version: combine many fast, focused checks with fewer integration and end-to-end tests; add security, performance, resilience, and production signals according to risk. Run the cheapest useful evidence early and reserve broad tests for the journeys that genuinely need them.
Start with risk, not test types
Before choosing tools, identify what could hurt users or the business. A pricing error, lost payment, privacy breach, inaccessible workflow, and slightly misaligned icon do not deserve the same testing investment. Rank scenarios by impact, likelihood, detectability, and how easily the failure can be reversed.
This creates a useful conversation between product, engineering, security, and operations. Critical flows receive deeper coverage and stronger release gates. Low-risk presentation changes may need a component check and focused review. Risk-based testing keeps quality work proportional instead of applying the same checklist to every change.
Build a balanced testing portfolio
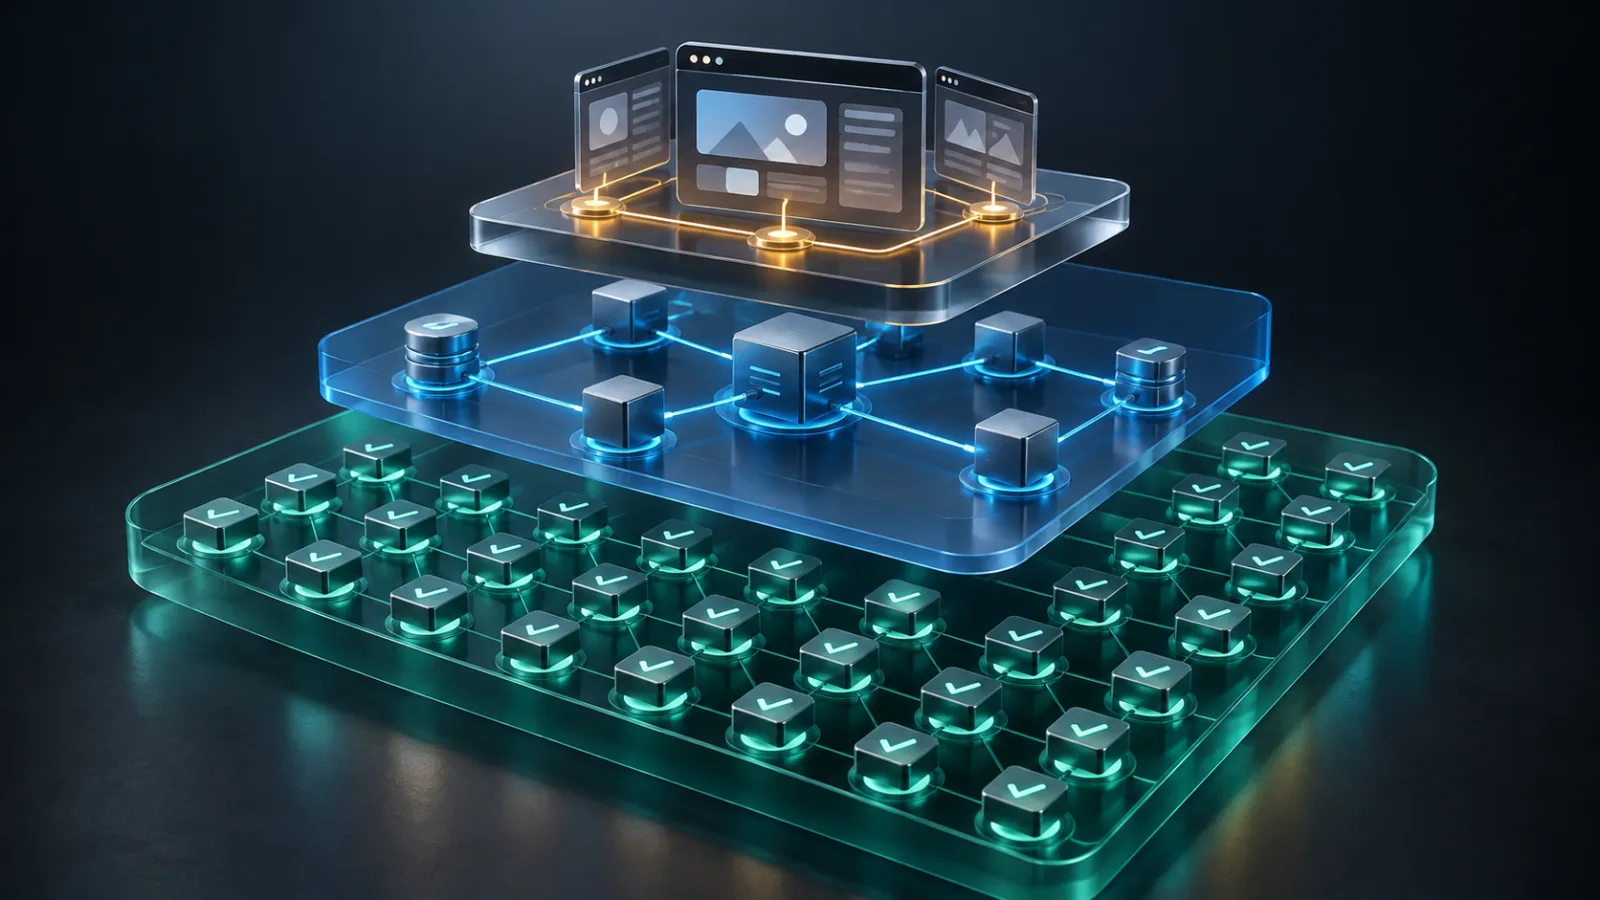
The familiar test pyramid remains a useful starting point: keep many checks close to the code and fewer tests at the broad user-interface level. I treat it as an economic model rather than a fixed ratio. Fast tests give precise feedback cheaply. Broad tests cover real integration paths but cost more to run, diagnose, and maintain.
- Unit and component tests protect calculations, domain rules, state changes, and boundary conditions. They should be deterministic and quick enough to run during development.
- Integration tests prove that code works with a real database, queue, cache, file system, or external adapter. Use them where mocks would hide important behaviour.
- Contract tests check that independently delivered services still agree on request and response shapes. They are especially useful when a full shared environment is slow or fragile.
- End-to-end tests protect a small number of valuable user journeys across the deployed system. Keep them focused. Repeating every edge case through the browser creates cost without better diagnosis.
Test the qualities users notice in production
Functional correctness is only part of software quality. A checkout that returns the right result in five seconds is still a poor checkout. Add performance tests around explicit latency and throughput objectives. Exercise timeouts, retries, idempotency, failover, recovery, and degraded dependencies. Verify accessibility with automation and human review.
Security testing belongs throughout delivery. Static analysis and dependency checks provide quick feedback, while threat modelling, targeted dynamic testing, and penetration testing cover different risks. The NIST Secure Software Development Framework integrates secure practices into the lifecycle, and the OWASP Web Security Testing Guide provides detailed web testing scenarios.
Put feedback at the right point in delivery
Developers need a fast local loop. Pull requests should run focused tests, linting, type checks, security scans, and the relevant integration suite. Broader regression, performance, and environment-level checks can run later when their cost is justified. A failed check must explain what broke; a red pipeline with no actionable diagnosis trains people to ignore it.
Tests should change with the production code. Google’s engineering guidance recommends adding appropriate unit, integration, or end-to-end tests in the same change and reminds reviewers that tests themselves need human scrutiny. Ask whether a test would fail for the defect it claims to detect. Coverage percentage alone cannot answer that.
Continue testing after release
Pre-release environments cannot reproduce every traffic pattern, dependency failure, or data shape. Feature flags, canary releases, synthetic journeys, observability, and rollback automation extend the strategy into production. These controls do not excuse weak pre-release testing; they reduce the cost of uncertainty that remains.
Track escaped defects, flaky-test rate, feedback time, change failure rate, and recovery time. Avoid rewarding raw test counts. Delete tests that duplicate stronger evidence, repair unreliable tests quickly, and investigate recurring production failures as gaps in the strategy rather than isolated mistakes.
Frequently asked questions
What is a software testing strategy?
It is a risk-based plan describing what the team will verify, at which layer, in which environment, with what data and automation, and which evidence is required before and after release.
How many end-to-end tests should a project have?
There is no universal number. Keep enough to protect the most valuable cross-system journeys, while testing most rules and edge cases at faster component and integration layers.
What should be automated first?
Automate stable, repeated, high-value checks that provide clear results. Keep exploratory testing, usability assessment, and investigation where human judgment adds more value.